
Somewhere in Santa Clara, NVIDIA CEO Jensen Huang is probably standing atop the ramparts of NVIDIA's magnificent castle, surveying the enormous and technically deep moat his company has spent nearly two decades digging around its GPU empire. It's deep, wide, stocked with crocodiles named cuBLAS and cuDNN, and guarded by thousands of software engineers who speak fluent CUDA — NVIDIA’s proprietary set of software products that translate PyTorch code into AI-ready applications. Happy customers abound in the land of CUDA, deploying NVIDIA GPUs, software and models for all manner of AI labors. The CUDA ecosystem has penetrated most knowledge-intensive industries, from biotech to manufacturing to video games. In a nutshell, it is the drawbridge that makes it easy for engineers to convert normal code into AI-ready applications, for inference and models running parallel processes that best use graphics processing units.
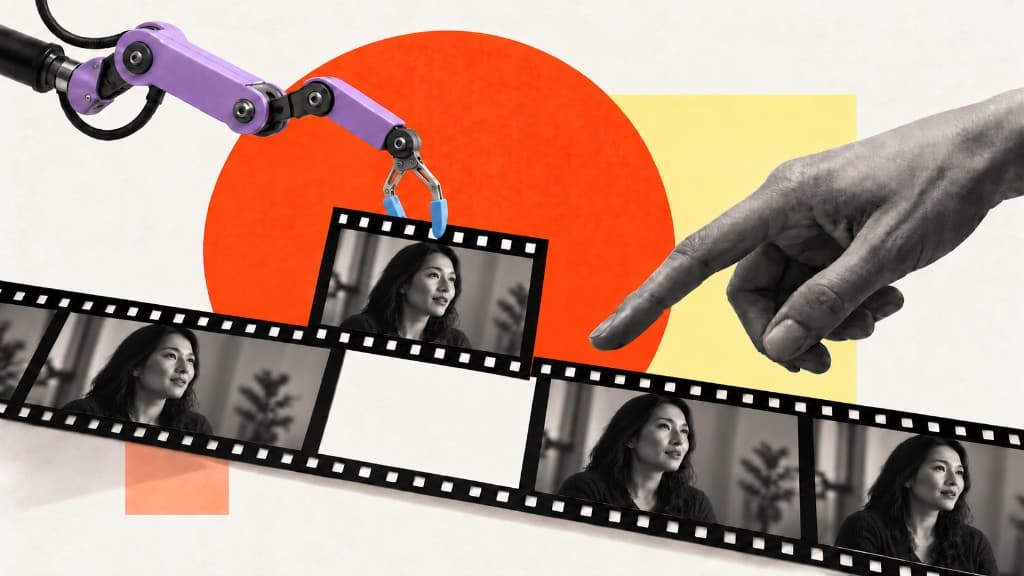
Now Amazon has shown up with an open-source drawbridge, and naturally, it's called TorchNeuron. Amazon's newly announced project promises to make running PyTorch models on its custom Trainium AI chips dramatically easier, potentially eliminating one of the biggest obstacles to escaping NVIDIA's expensive embrace. The interesting part isn't that Amazon has another chip to sell, but that it's attacking the software dependencies that have made NVIDIA extraordinarily difficult to dislodge. Of course, TorchNeuron is tightly tied to Amazon’s cloud ecosystem and the company believes that this tie-in is a feature that will make building and then running all of the things around AI apps easier, faster, and cheaper. So it’s open source but mostly benefiting Amazon — for now. In the future, TorchNeuron could presage efforts to further erode the CUDA gap and allow all the hyperscalers and frontier labs that are building their own chips (meaning, almost all of them) to improve operating margins by vertically integrating more of their AI business around a seamless chips-and-software combo.
The PyTorch Connection
Most AI developers build models using PyTorch, the open-source machine-learning framework originally developed by Meta and now governed by the Linux Foundation's PyTorch Foundation. While PyTorch is designed to work across different hardware architectures, NVIDIA has made its GPUs the path of least resistance through years of relentless software optimization. And, talking to anyone in AI, you understand how good a job NVIDIA did with this. CUDA is widely respected and used because it delivers largely on its promises.
TorchNeuron potentially changes that equation by letting developers use familiar PyTorch APIs with Trainium, including eager execution, compilation and distributed training. For compatible workloads, migration can be as simple as changing the target device, rather than rebuilding applications around an entirely different software stack. For startups watching their AI computing bills balloon like a Thanksgiving parade float, that's a compelling proposition, especially if Trainium delivers meaningful cost savings. With CUDA as such an obvious target, logically, others have targeted it, specifically AMD with its ROCm product and ecosystem, which is also notably open source. Amazon is a different kind of incursion, because it does control not just the silicon but the entire AI stack inside the AWS ecosystem.
More than a Translational Layer, CUDA Is an Entire Civilization
It’s entirely possible that NVIDIA's advantage isn't a single programming interface but an enormous collection of specialized libraries, tools and optimizations accumulated over nearly twenty years. Its CUDA-X ecosystem includes cuBLAS and cuDNN for mathematical operations, NCCL for coordinating massive GPU clusters, and specialized libraries for everything from scientific simulation to industrial computing. TorchNeuron can make PyTorch applications portable, but it cannot automatically reproduce all those performance advantages, particularly when developers rely on custom CUDA kernels or specialized optimization frameworks. Additionally, NVIDIA is the largest publisher of open-weight AI models, with literally hundreds of flavors. Naturally, these models are exquisitely tuned to speak CUDA. The recent Hugging Face acquisition by NVIDIA further cements the firm’s position as the top provider of open-weight models, a market consideration that is growing in importance as AI sovereignty becomes more of a thing.
The challenge gets tougher with production AI systems, where technologies such as vLLM, SGLang and FlashAttention squeeze every possible drop of performance from expensive hardware. Amazon has its own Neuron Kernel Interface and optimization tools, but translating hand-tuned CUDA code into equally efficient Trainium implementations remains an engineering problem rather than a magical compiler trick. The TorchNeuron beta also has limitations involving dynamic shapes, attention operations and certain quantization integrations, reminders that supporting a workload and running it competitively are different accomplishments. Here is where Amazon’s scale makes things interesting — because it has sufficient leverage to encourage Day Zero compatibility for new improvements on the kernels and inference engines that actually run most workloads above the silicon.
Although TorchNeuron is released under Apache 2.0 and contributes to PyTorch's hardware independence, the backend itself is designed specifically for AWS Trainium. Amazon is effectively offering developers an escape route from NVIDIA's walled garden into another walled garden. Still, greater portability could have consequences far beyond Trainium by weakening the assumption that serious AI development inevitably means buying NVIDIA hardware. If competing accelerator vendors can make migration easier while offering better economics, customers gain leverage even when they ultimately remain with NVIDIA. Also, because Amazon released TorchNeuron under Apache 2.0, it could well be forked and adapted to other silicon variants tuned for AI applications. Amazon is reportedly seeking outside contributors to help build up the TorchNeuron ecosystem capabilities in a bid to better compete with all the various flavors and varieties of CUDA specialization.
So, Is NVIDIA’s CUDA Moat At Immediate Risk?
Amazon is testing a strategy quite different from previous attempts to challenge CUDA by announcing faster chips and steadily improving an NVIDIA competitor while constantly racing to keep up with breakneck NVIDIA improvements and additions to its own CUDA domain. Amazon will test the thesis that you don't necessarily have to destroy NVIDIA's CUDA moat if you can make crossing it sufficiently painless or beneficial in other ways. The real test won't be whether a PyTorch demo runs successfully on Trainium, but whether production teams can migrate complex workloads, preserve performance and substantially reduce their costs without hiring an army of compiler engineers. Net-net, this is a good thing for competition, a good thing for open source, and probably a good thing for both Amazon and NVIDIA if it grows the AI pie even more.