Forward Future Tools Library

AnyCrawler logo

AnyCrawler

AnyCrawler gives developers API access to live web search, page extraction, JavaScript rendering, Markdown output, and screenshots for AI agents, RAG systems, and research workflows.

Try AnyCrawler →

anycrawler.com·Free + paid plans·Checked 2026-10-12
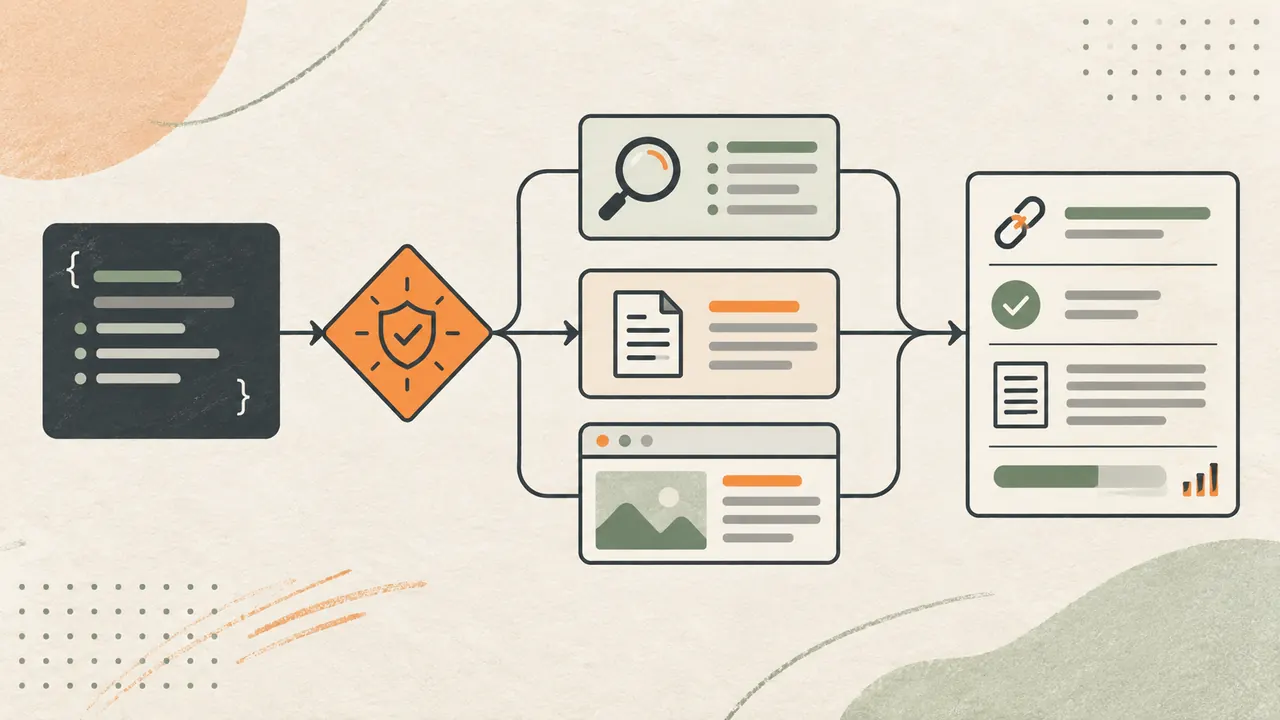
Agent-Safe Web Access Tool Contractanycrawl-testing-the-llm-ready-web - The Web Scraping Wiki by The Web  Scraping ClubOpen Source Web Crawlers in 2026: 7 Tools ComparedAnyCrawl: Testing the LLM-Ready Web Scraping Service
Agent-Safe Web Access Tool Contractanycrawler.com
Agent-Safe Web Access Tool Contract
Agent-Safe Web Access Tool Contractanycrawler.com

›What is AnyCrawler?

AnyCrawler is a web data API for AI applications that need current public web content. Developers can search web, image, news, video, and scholarly sources, then fetch known URLs or render JavaScript-heavy pages into clean Markdown. Separate screenshot endpoints return viewport or full-page PNGs.

›What are the pros and cons of AnyCrawler?

Strengths

Combines search, page extraction, browser rendering, and screenshots in one API
Returns readable Markdown instead of requiring downstream HTML cleanup
Supports multiple search channels, including news, video, and scholarly sources
Offers a one-time 5,000-credit free plan for testing
Provides an Agent Skill as well as standard API workflows

Trade-offs

Usage is credit-based, and render and screenshot requests consume substantially more credits than fetch requests
The Free plan has a one-time credit grant rather than recurring monthly credits
Throughput and browser concurrency are capped by plan, with the Free plan limited to 30 fetch requests per minute and one browser slot
JavaScript-heavy pages require the more expensive Render path instead of Fetch

›What are AnyCrawler’s key features?

Web, image, news, video, and scholar search APIs
Fetch API for extracting content already present in a page's HTML
Render API for JavaScript-loaded pages and browser-dependent content
Clean Markdown responses with optional metadata, links, and media
Viewport and full-page screenshot APIs
Agent Skill setup for adding live web access to AI agents
API keys, usage logs, and credit-based billing

›What are the best use cases for AnyCrawler?

Give AI agents current public web context during an agent workflow
Ground RAG pipelines with Markdown extracted from live pages
Build research tools that combine web, news, image, video, or scholarly results
Collect content from JavaScript-heavy sites for downstream analysis
Capture screenshots as visual evidence alongside extracted page content

›What is the pricing for AnyCrawler?

PlanPriceDetails
Free$0/mo5,000 one-time credits, 30 fetch requests per minute, and 1 browser concurrency slot.
Agent Lite$5/mo15,000 monthly credits, 60 fetch requests per minute, and 2 browser concurrency slots.
Builder$20/mo80,000 monthly credits, 180 fetch requests per minute, and 3 browser concurrency slots.
Growth$80/moPlan for teams scaling production usage.

Base costs are 2 credits per fetch, 10 per render, 2 per returned search result, 20 per viewport screenshot, and 50 per full-page screenshot. Optional crawl fields add credits, while valid cached renders can cost 1 credit.

Checked 2026-10-12 · source

›Who is AnyCrawler best for?

developersA fit for developers who want API endpoints for search, crawling, rendering, and screenshots without building browser infrastructure.
RAG engineersUseful for grounding retrieval pipelines with current public pages returned as clean Markdown.
research automation teamsThe multiple search channels and screenshot support suit automated web and source-gathering workflows.
small teamSmall teams can prototype with the one-time Free credits and move to monthly plans as usage becomes regular.
Not for
  • Non-technical users who need a point-and-click scraping product rather than API and agent setup.
  • Teams requiring very high-volume scraping without plan-based request, credit, and browser-concurrency limits.
  • Projects focused on social media extraction, which is not listed among the supported capabilities.
›What are the best AnyCrawler alternatives?

›Where can I try AnyCrawler?

Open anycrawler.com →